A product with 100 users can hide a lot of problems.
A product with 100,000 users usually cannot.
In the early days of building software, the priority is often simple: get it working. The team is small, deadlines are tight, requirements keep changing, and getting the product into users’ hands matters more than making every technical decision perfect.
And that is completely reasonable.
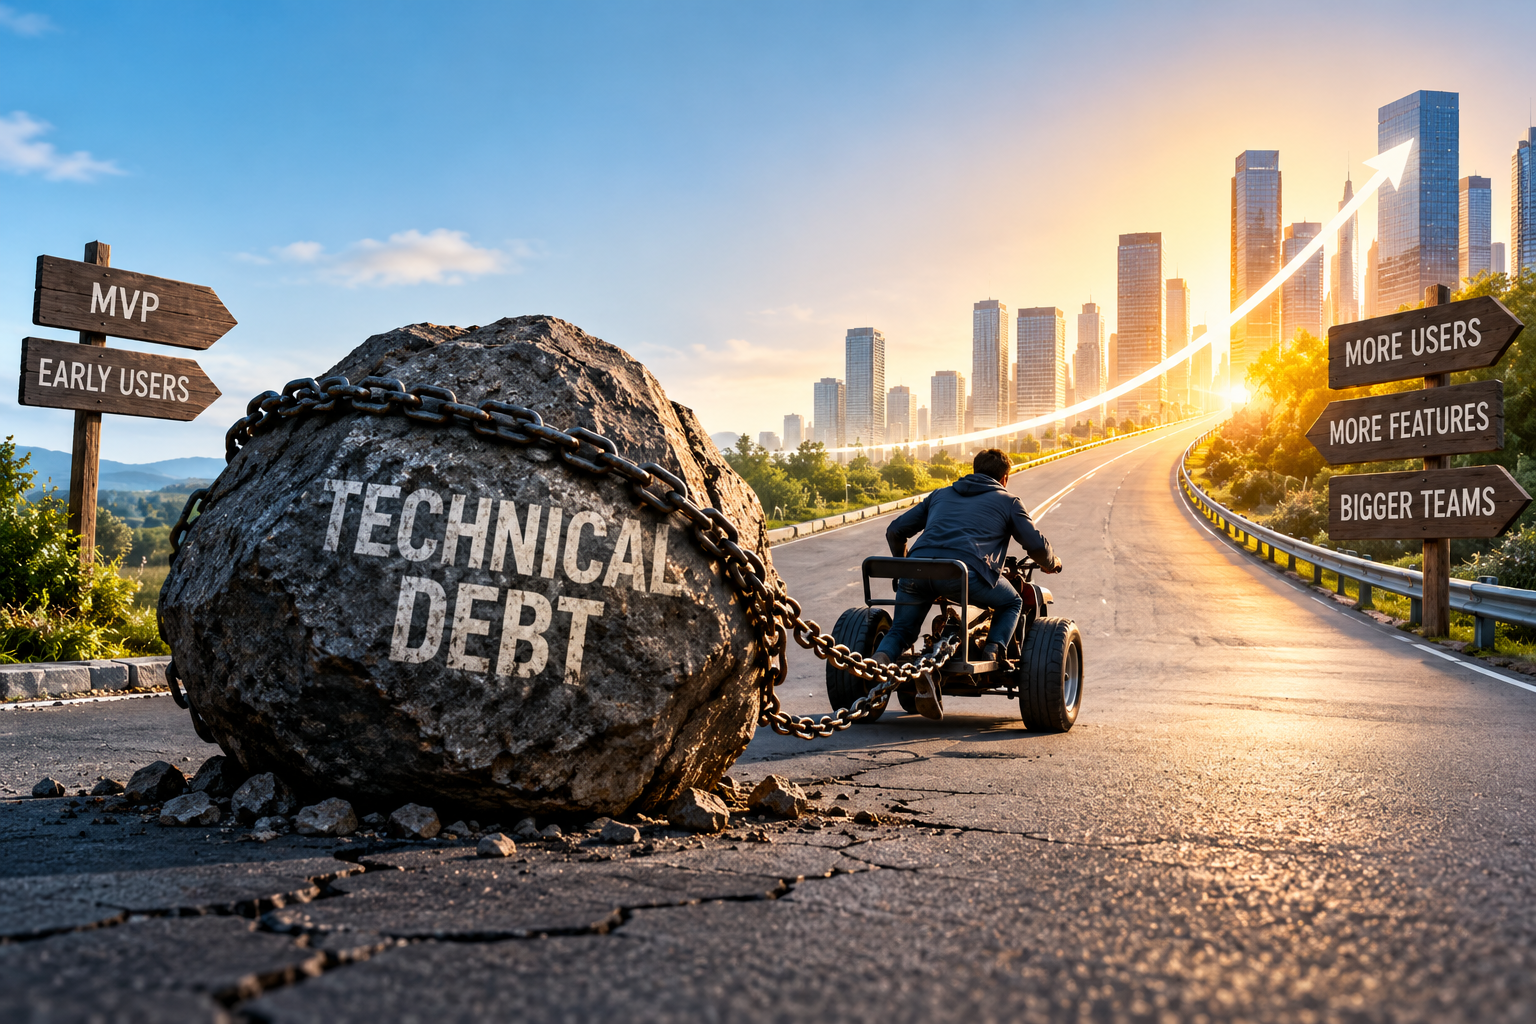
The problem starts when temporary decisions quietly become permanent ones.
A shortcut taken to meet a deadline stays in the codebase. A database structure designed for a small number of users never gets revisited. A manual process works well enough, so nobody automates it. One feature gets added on top of another until changing something in one place unexpectedly affects three other parts of the application.
Everything still works.
Until the product starts growing.
Technical Debt Isn’t Always Bad Code
When people hear "technical debt," they often imagine messy code or poor development practices.
But technical debt is broader than that.
It can be any technical decision that makes sense today but creates additional work tomorrow.
Sometimes the team knows about it.
"We’ll clean this up after launch."
Sometimes they don’t.
A system may have been designed perfectly well for the business it supported at the time. The problem is that the business changed while the architecture didn’t.
More customers arrived.
More developers joined.
More integrations were added.
More data started moving through the system.
Suddenly, decisions that were invisible at a smaller scale begin showing their cost.
Growth Changes the Rules
Imagine an application that processes 500 requests every day.
A database query taking slightly longer than necessary probably isn’t a serious concern. A manual deployment may only take a few minutes. An occasional background job failure can be restarted by a developer.
Now imagine the same application processing hundreds of thousands of requests.
That inefficient query is being executed constantly.
Deployments happen more frequently because several developers are contributing to the product.
Background jobs are handling important customer activity.
The underlying problems haven’t necessarily changed.
Their impact has.
Growth acts like a magnifying glass for technical debt.
Small inefficiencies become performance issues. Minor architectural limitations become scaling problems. Manual processes become operational bottlenecks.
And that is usually when teams start noticing debt they didn’t realize they had.
The Database Usually Knows First
One of the first places growth becomes visible is the database.
During early development, teams naturally optimize for simplicity. Queries work quickly because there isn’t much data to search through.
Then the dataset grows.
Thousands of records become millions.
Pages that loaded instantly begin taking several seconds. Reports become slower. Search becomes inconsistent. Certain API requests suddenly consume far more resources than expected.
The instinct is often to add more infrastructure.
Sometimes that is necessary.
But sometimes the real problem is much simpler: the application is asking the database to do work inefficiently.
Missing indexes, unnecessary queries, poor data models or repeated database calls may have existed from the beginning.
Scale simply made them visible.
Every Shortcut Eventually Finds an Audience
Early-stage products often contain shortcuts because they need them.
Perhaps notifications are handled synchronously because building a proper queue would take additional time.
Maybe permissions are simple because there are only two types of users.
Maybe several parts of the application are tightly connected because separating them would slow down the initial release.
None of those decisions automatically means the engineering was poor.
Context matters.
The mistake is assuming the context will never change.
If the number of users increases, the notification system may struggle.
If enterprise customers arrive, permissions may suddenly need multiple roles and approval levels.
If development expands across several teams, tightly connected components can make seemingly simple changes increasingly risky.
Technical debt becomes expensive when yesterday’s assumptions continue driving tomorrow’s system.
More Developers Can Actually Make the Problem More Visible
Growth doesn’t only mean more users.
It often means a larger engineering team.
With three developers, everyone may understand most of the application.
With thirty developers, that becomes much harder.
Unclear architecture, inconsistent coding patterns, missing documentation and tightly coupled components create friction.
A developer changes one module without realizing another depends on its behavior.
Someone builds functionality that already exists elsewhere.
Different teams solve the same problem in different ways.
Code reviews take longer because understanding the impact of a change becomes difficult.
At that point, technical debt starts affecting something beyond application performance.
It affects development speed.
Ironically, the company may hire more developers to build faster while the existing architecture makes every developer slower.
The Most Expensive Technical Debt Is Often Invisible
A slow page is easy to notice.
A failed deployment is obvious.
Some forms of technical debt are much quieter.
They appear as:
"We shouldn’t touch that module."
"Only one developer really understands this."
"That release needs to happen manually."
"We don’t know what will break if we change it."
"Testing the whole thing takes too long."
Those sentences should get attention.
They indicate that knowledge, processes or architecture may have become fragile.
And unlike a visible bug, these problems can remain hidden for months.
Until the person who understands that module leaves.
Until the company needs to release quickly.
Until an important customer requests a change.
Then invisible technical debt becomes very visible.
Should We Remove All Technical Debt?
Probably not.
Trying to eliminate every piece of technical debt can be just as damaging as ignoring it.
Software development always involves trade-offs.
Sometimes shipping a feature today is genuinely more valuable than spending another month designing the perfect architecture for a future that may never arrive.
The important question isn’t:
"Do we have technical debt?"
Almost every evolving product does.
A better question is:
"Do we know which technical debt could become a problem if we grow?"
That changes the conversation.
Teams can identify areas where growth will increase risk and prioritize accordingly.
A system expected to handle significantly more traffic deserves attention.
A component that changes once every three years probably deserves less.
Technical debt should be managed according to impact, not perfection.
Build for the Next Stage, Not the Final Stage
There is another trap on the opposite side of technical debt: overengineering.
If an application has 1,000 users, designing infrastructure for a hypothetical billion users may not be the best use of the team’s time.
You don’t need to predict every possible future.
You need to understand what is likely to break next.
Can the database handle 10x the current data?
Can deployment remain reliable as the development team grows?
Can critical components be monitored?
Can another developer understand the system without asking the person who originally built it?
Can one part of the application change without creating unexpected problems somewhere else?
Those questions are often more useful than asking whether the architecture is "perfect."
Because perfect architecture doesn’t exist.
Architecture that can evolve does.
Growth Doesn’t Create Technical Debt. It Reveals It.
When a growing application begins experiencing performance problems, slow releases or engineering bottlenecks, it is tempting to blame scale.
But scale often isn’t the original problem.
It simply exposes decisions that no longer fit the environment.
The architecture that worked for the first version of the product may not be the architecture needed for the next version of the business.
That doesn’t mean the original decisions were wrong.
It means their time has passed.
Good engineering isn’t about predicting every future problem before writing the first line of code.
It is about recognizing when the assumptions behind yesterday’s decisions have changed and being willing to change the system with them.
Because technical debt rarely announces itself when you create it.
Most of the time, it waits quietly.
Then the product grows.